News
Keeping you up to date on news, events and what’s happening at ESG…

Keeping you up to date on news, events and what’s happening at ESG…
By Andrew Green, Chief Technical Officer at ESG.
An AI agent flags a billing exception. It knows the likely cause. It determines the correction. It has permission to make the change.
The fix takes seconds. No employee reviews it. No ticket gets created. No one touches the transaction.
That’s the promise of agentic AI. But what happens when the AI is wrong?
For years, the conversation in retail energy has been about whether AI can help us understand what happened, predict what’s likely to happen next, and recommend what to do about it. That work has real value. It creates meaningful opportunities to improve efficiency and reduce the manual effort required to run increasingly complex energy businesses.
The bigger economic opportunity now isn’t having AI tell us what to do. It’s giving AI permission to do it.
AI agents are increasingly capable of identifying exceptions and making decisions. They can take action across business processes without waiting for a person to intervene. An agent could recognize a customer issue and initiate the communication. It could detect an operational exception and resolve it according to a defined set of rules.
The potential is significant, and so is the risk. The economics of autonomous AI aren’t simply about how much work it can eliminate. They’re about what happens when it gets something wrong.
Retail energy organizations have no shortage of reasons to automate. Margins are under pressure. Customer expectations continue to rise. Products and pricing are becoming more complex. Operations teams are expected to manage more data without adding proportional headcount.
Automation is an obvious answer. If a person spends five minutes resolving an exception and an AI agent can resolve it in seconds, the economics seem straightforward. Multiply that across thousands or millions of transactions and the potential savings become substantial.
But what if the AI makes the wrong decision?
The cost of an error isn’t equivalent to the cost of the work that was automated. Saving five minutes of employee time doesn’t justify creating a $5,000 billing error. Avoiding ten minutes of manual review isn’t worthwhile if the resulting mistake affects a customer’s account, creates a regulatory issue, or propagates into downstream systems.
Those two numbers don’t scale the same way, and that’s where the economics of AI get complicated.
There’s an important distinction between AI that supports a decision and AI that makes one. Consider the progression:
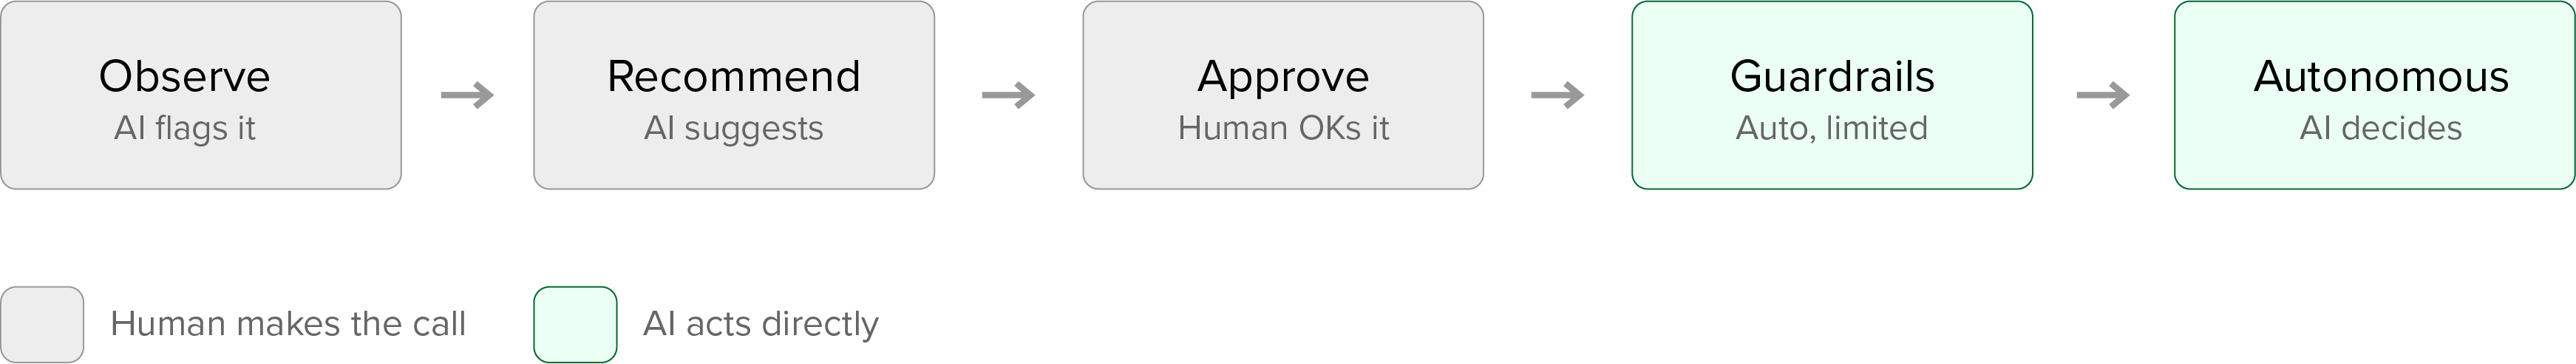
The autonomy spectrum — none of these stages is inherently better than another
None of these stages is inherently better than another, and the mistake is assuming every process should eventually reach the final one. The right level of autonomy depends on the decision. That means the real question isn’t “How much of this process can we automate?” It’s “How much autonomy should we give AI for this particular decision?”
Imagine an AI agent monitoring billing exceptions. For a simple, well-understood exception with a known resolution, the case for autonomous action is strong. The financial impact is limited, the appropriate response is predictable, and the action can be reversed if necessary.
Now consider a disputed customer charge, an unusual contract provision, or a transaction with regulatory implications. The same level of autonomy no longer makes sense. The AI may still be valuable as it can gather the relevant information, identify the issue, recommend a resolution, and prepare the necessary action. But the final decision may belong with a person.
Autonomy has to be evaluated decision by decision, against a few specific questions.
How much time, cost, or operational capacity does autonomous action actually create? If the savings are marginal, there’s little economic justification for accepting additional risk.
“Downside” isn’t one number. It breaks into at least four distinct kinds of risk, and a given decision can carry more of one than another:
A decision can score low on financial risk and high on regulatory risk, or the reverse. Treating “downside” as a single figure hides that distinction. It hides exactly the cases where autonomy is riskier than it looks.
Retail energy operations are interconnected in a way that makes this question harder than it sounds. A single exception can touch a long chain of downstream processes:
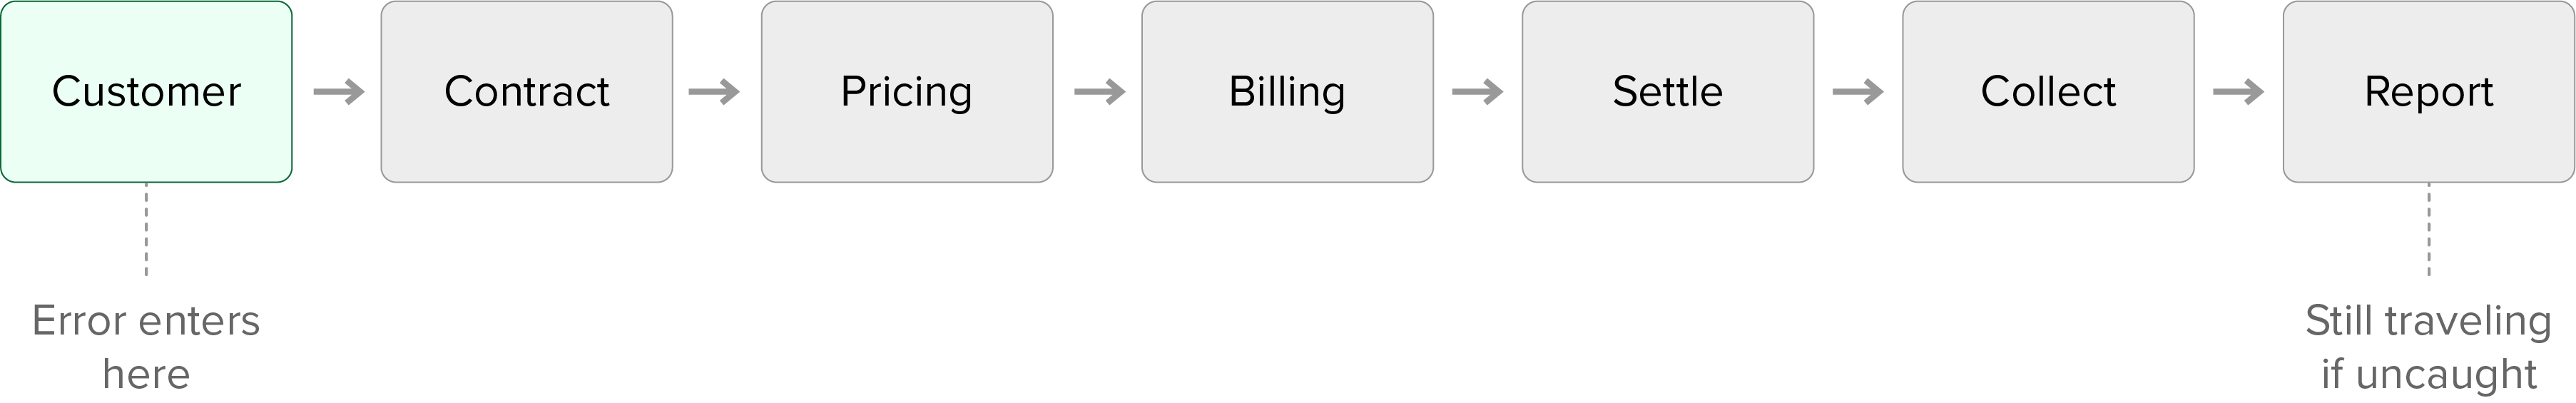
An error caught early is a conversation. Caught late, it’s a cleanup
An AI agent rarely acts on just one link in that chain. The more of it an agent can influence, the more valuable it becomes. This could allow a single wrong decision to travel further before anyone notices. An error caught at the customer step is a conversation. The same error, uncaught, can still be propagating by the time it reaches settlement or reporting.
This may be the single most useful question in the framework. Some actions are highly reversible, while others aren’t. Sending a draft for human review is reversible. Sending the customer communication is less so. Correcting a transaction may be possible, but reversing the downstream consequences of that transaction may be considerably harder. The less reversible an action is, the more evidence and control should be required before giving AI the authority to take it.
Trust shouldn’t be an assumption. Before an AI agent is given greater autonomy, organizations should have evidence that it performs consistently within a defined environment. They should observe its error rates, its decision patterns, clear boundaries, and a known point at which it escalates rather than acts. Autonomy should be earned through performance, not granted simply because the technology is capable of it.
The obvious response to AI risk is to keep a human involved, and for some decisions, that’s exactly right. But “human in the loop” isn’t a complete strategy.
If an organization asks employees to manually approve every AI-generated decision, it may simply move the bottleneck rather than eliminate it. An operations team reviewing thousands of AI recommendations every day can become an expensive human verification layer sitting on top of an automated process. And humans aren’t infallible. People make mistakes, miss patterns, get tired, or approve decisions without enough context.
So the goal isn’t to put a human in front of every AI decision. It’s to put the right control around the right decision. High-impact decisions, automated monitoring for lower-risk actions, predefined thresholds, transaction limits, and audit trails need human approval. Or ensuring automatic escalation when an agent encounters something outside its expected operating range. The objective isn’t maximum human involvement. We want appropriate human involvement.
Which brings us back to the question in the title: what does trust actually cost?
Giving an AI agent more autonomy has an economic benefit. It removes human intervention. But limiting that autonomy also has a cost. If every decision requires manual review, the organization gives up some of the efficiency it hoped AI would create. If no decisions require review, it may expose itself to unacceptable risk. The optimal point sits somewhere between those extremes, and it’s different for different processes, companies, and decisions. It can also change over time.
An AI agent that initially requires human approval for every action may eventually demonstrate enough consistency to operate within defined boundaries. As its performance is measured and understood, those boundaries can expand.
That creates a different model for AI adoption. Instead of asking how quickly an organization can move from human work to autonomous AI, leaders should ask how quickly AI can demonstrate that it deserves more responsibility.
The objective shouldn’t be to make AI as autonomous as possible. It should be to make AI as autonomous as the economics and risk allow.
That means starting with processes where the value of automation is clear and the consequences of failure are manageable, establishing controls, measuring performance, and understanding where the technology succeeds and where it struggles. Then, where the evidence supports it, autonomy can increase.
The progression looks something like this:

Trust runs through every stage. Without reliable data, AI can’t make reliable decisions. Without meaningful analytics, there’s little foundation for intelligent action. Without appropriate automation, AI recommendations stay disconnected from the processes they’re meant to improve. And without controls, autonomy can turn efficiency gains into operational risk.
The organizations that benefit most from agentic AI may not be the ones that automate the most. They may be the ones best at determining where AI should act, where it should recommend, and where a person should remain responsible.
AI will keep getting more capable. The question is no longer whether it can perform tasks that previously required human intervention. We’ve seen that increasingly, it can. The harder question is where it should be allowed to act without us.
For retail energy, that matters because operational processes are interconnected. The same customer-to-reporting chain that makes a well-placed AI agent valuable is what makes a wrong decision expensive. The more authority an agent has across that chain, the more value it can create, and the more it can cost when something goes wrong.
None of this means organizations should slow down their adoption of AI. It means they should become more deliberate about autonomy. Before giving an AI agent permission to act, ask:
None of this means organizations should slow down their adoption of AI. It means they should become more deliberate about autonomy. Before giving an AI agent permission to act, ask:
The future of AI in retail energy won’t be determined by how autonomous AI becomes. It will be determined by where autonomy creates more value than risk.
AI doesn’t need to earn our trust by being perfect. It needs to earn enough trust to be given the right responsibility.